- Chose
- Embeddings compared by cosine similarity.
- Instead of
- Matching on category, location and date with a database query.
- Why
- People describe the same object in different words, and a query only matches words. Embeddings match meaning. The cost is an external API call for each new piece of text, and a score that needs a threshold somebody has to choose.
WorkAcademic
Lost and found tracking system
BRAC University · 2025
A Flask application for reporting lost and found items on campus, built by a team of four for CSE471, System Analysis and Design. My part was reporting, the engine that matches lost reports with found ones, and sharing a report to social media. Teammates built login and the admin panel, the chat, and ownership verification.
PythonFlaskSQLAlchemyPostgreSQLGemini embeddingsscikit-learnSocket.IOBootstrap
The problem
Campus lost and found runs on noticeboards and group chats, so the two halves rarely meet: the person who lost a bag and the person who found it post in different places, days apart, in different words. A lost “brown wallet” and a found “brown leather wallet” are the same item to a person and two different strings to a database.
The system
Report
lost or found, one table
Embed
Gemini, cached on disk
Compare
cosine similarity
Score
same category +0.2
Notify
0.5 or above
Reporting
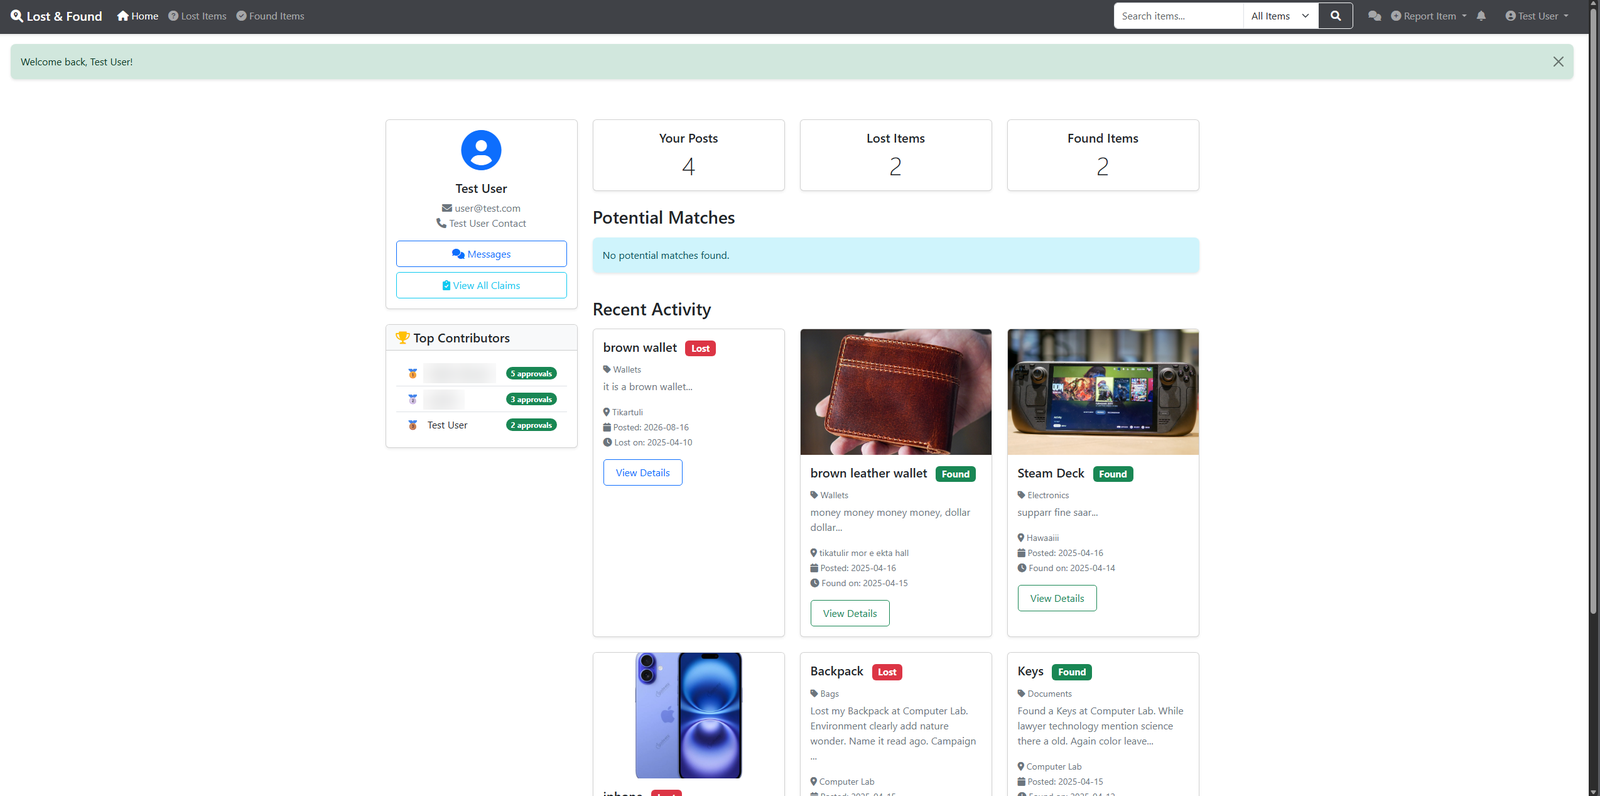
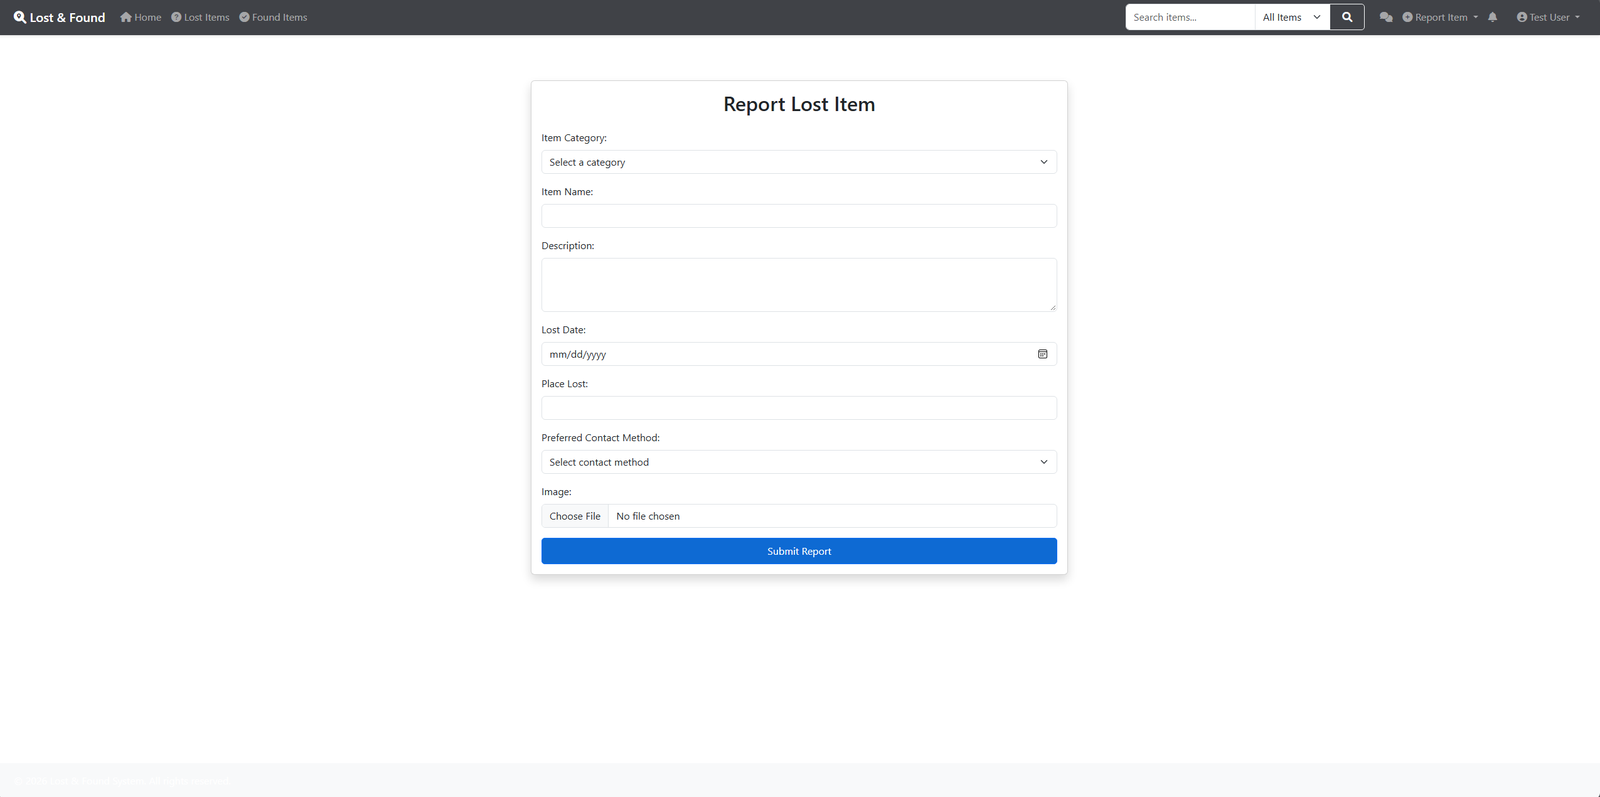
Lost and found reports are one model with a type, so matching is a query across one table. A report carries a category, name, description, place, date, preferred contact method and an optional image.
Matching by meaning
Each report's name, description, category and location become one Gemini embedding, compared with every report of the opposite type by cosine similarity. A shared category adds 0.2, and anything scoring 0.5 or above appears under Potential Matches, with a notification that states the score.
Embeddings cached on disk
The text is hashed and its embedding stored locally, so the same text is only ever sent to the API once, however many comparisons it takes part in.
Sharing a report
A report can be posted to Facebook, X, WhatsApp or Telegram through each platform's share link, prefilled with the item's details. No API keys and no accounts to connect.
Built by teammates
Login and roles, the admin panel, real-time chat over Socket.IO, and ownership verification, where a claimant has to supply details the public listing leaves out.
Technical decisions
What was chosen, what was chosen against, and what the trade cost.
- Chose
- A disk cache keyed by a hash of the text.
- Instead of
- Calling the embedding API on every comparison.
- Why
- Each new report is compared with every report of the other type, so without a cache the same descriptions would be embedded again with every post. A repeat costs nothing, and an edited report hashes differently and gets a fresh embedding.
- Chose
- A category bonus on top of the similarity score.
- Instead of
- Similarity alone.
- Why
- Descriptions of different kinds of object can read alike. A shared category is cheap, reliable evidence that two reports are about the same kind of thing, so it lifts like with like above the threshold.
- Chose
- Notifying with a score, never resolving a match automatically.
- Instead of
- Closing a pair above a confidence threshold.
- Why
- The two failure directions are not symmetric. A missed match wastes a little time; a wrong automatic match hands someone else's property away and the system was the one that decided it. Keeping a person in the loop costs a click.
The result
A working platform, deployed on Render for the course. The part I would talk about is the matching: pairing reports by what they mean rather than by the words they share, with a person confirming every match.